Connect production, configure the rules once and deliver realistic, reversible data to every environment that needs it: development, test, analytics and AI.
Every screen below is the actual Pseudia console. Take a look at how a team configures and runs pseudonymisation day to day.
Create workspaces for each team or department (BI, analytics, engineering) and let each one configure its own data sources and environments independently.
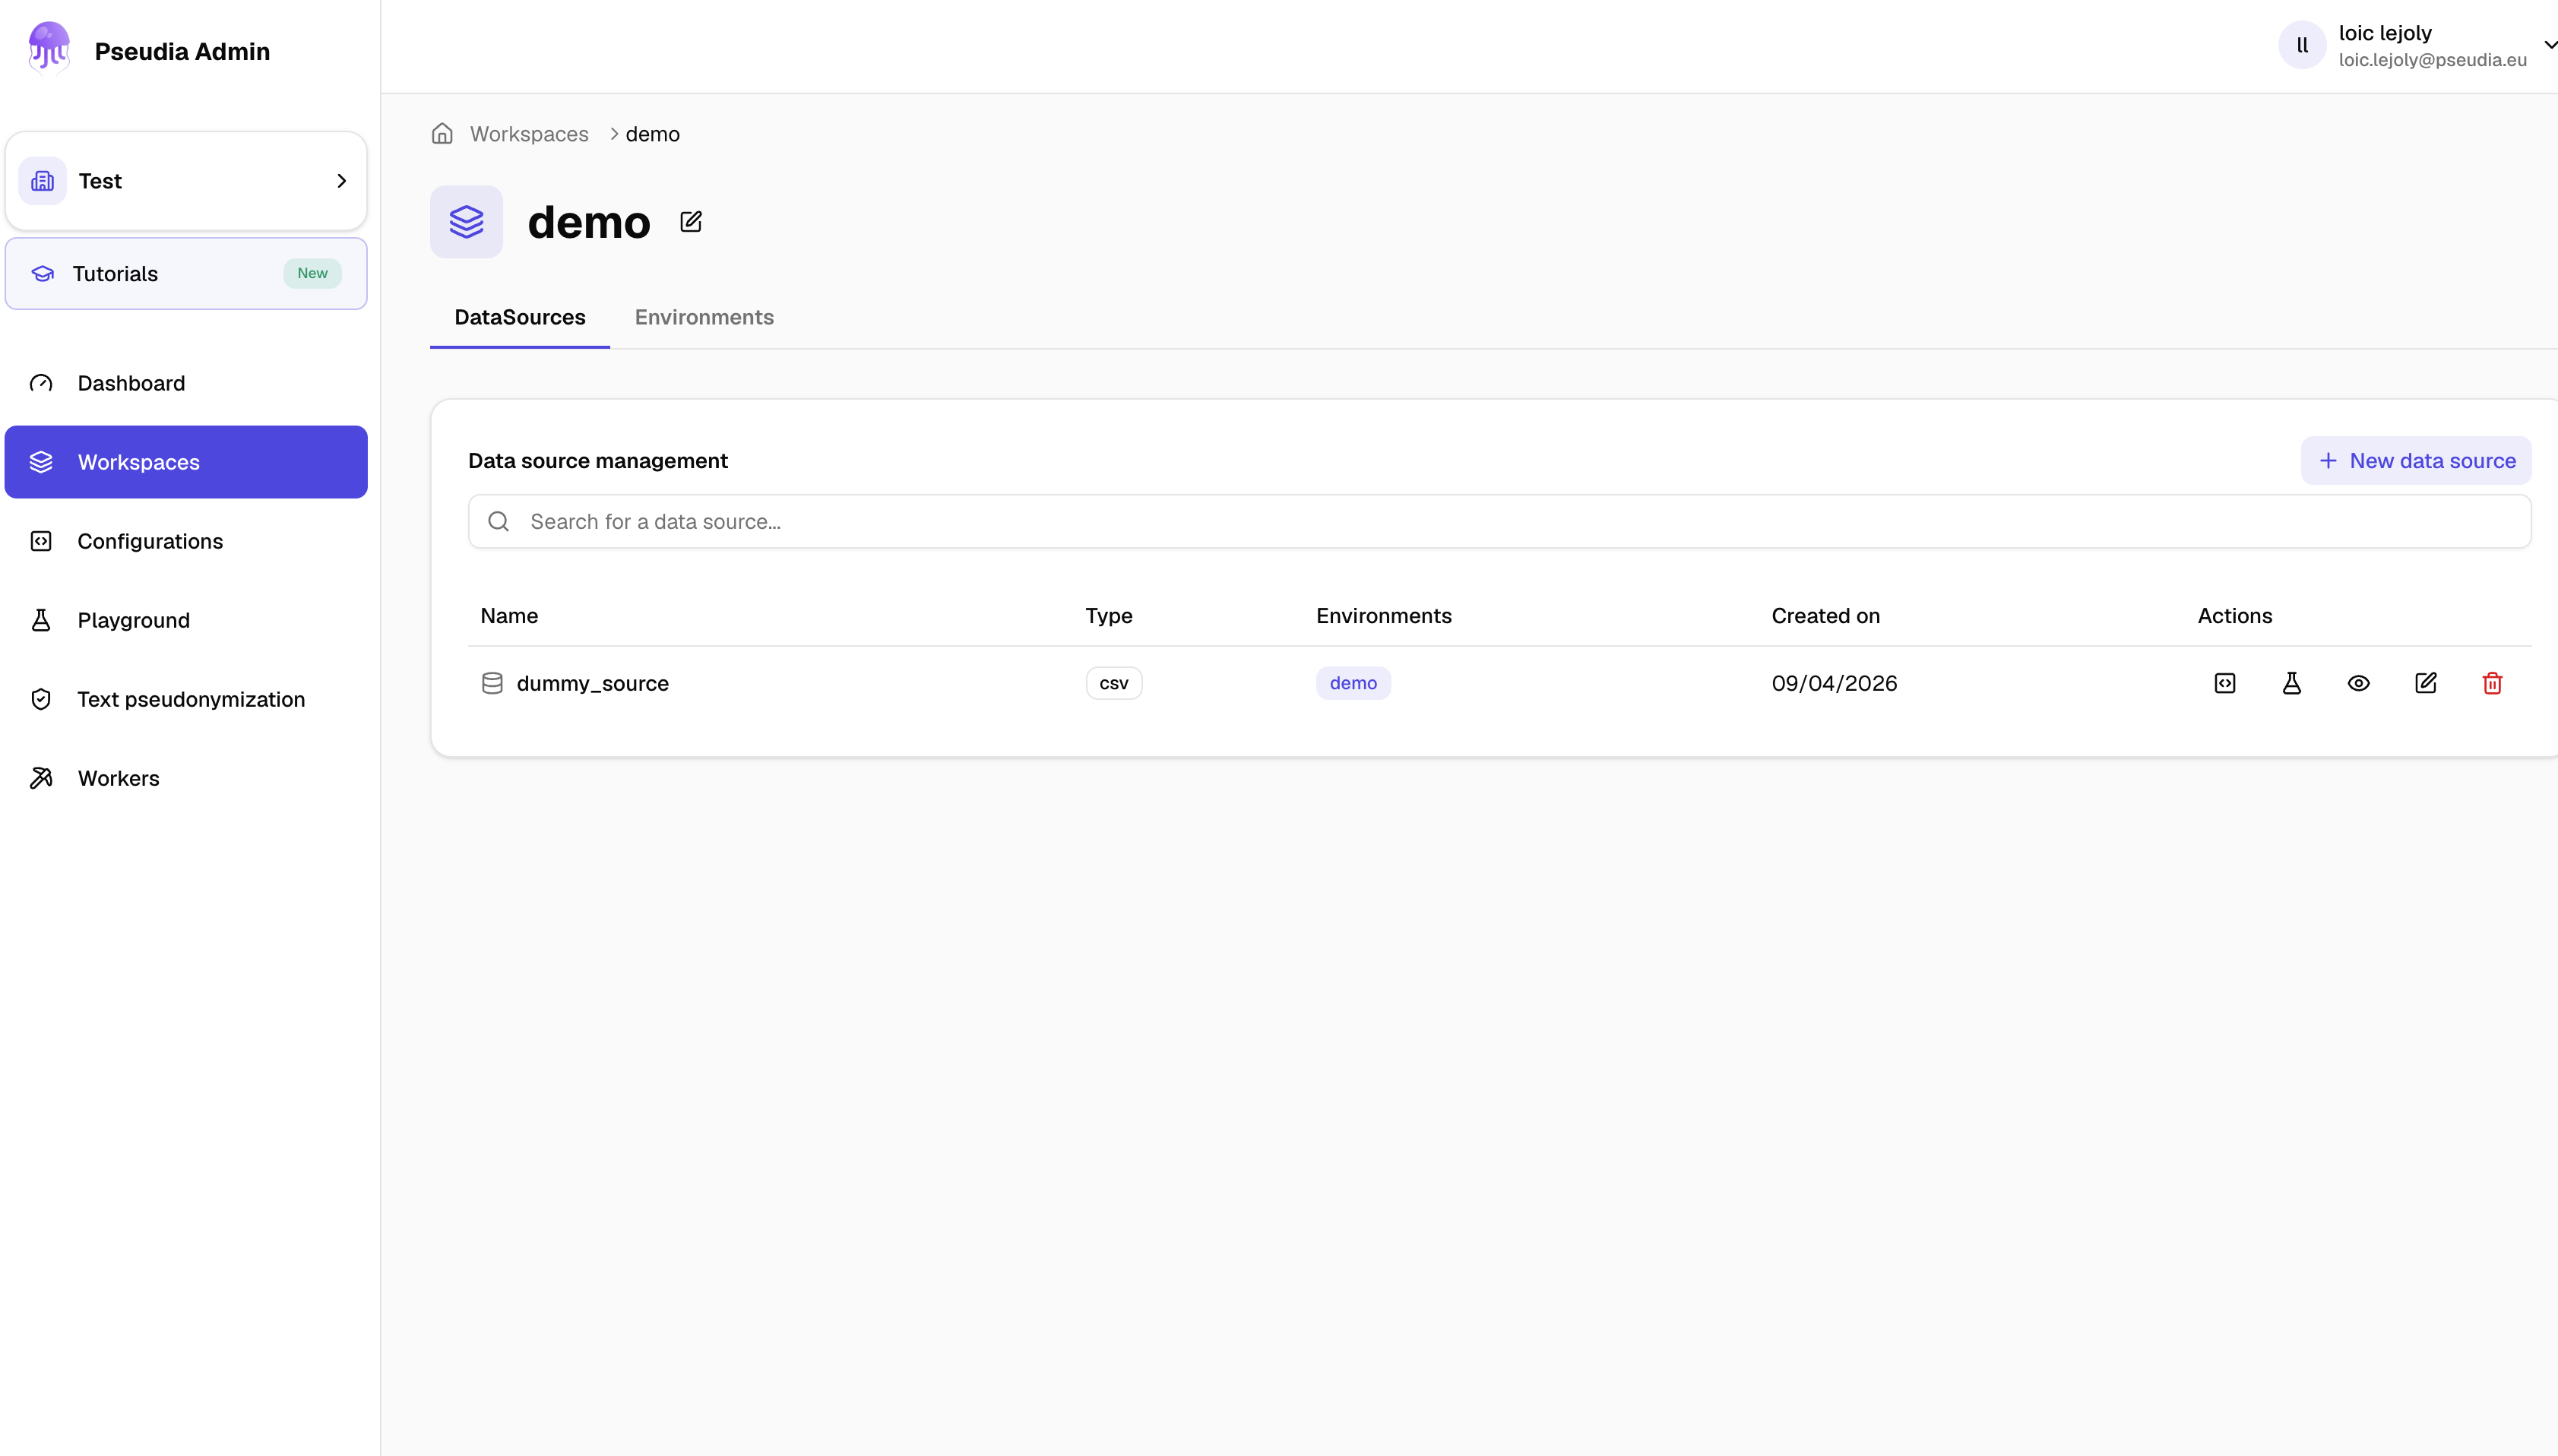
Link a configuration to a data source and pick exactly which fields must be pseudonymised, down to the individual column.
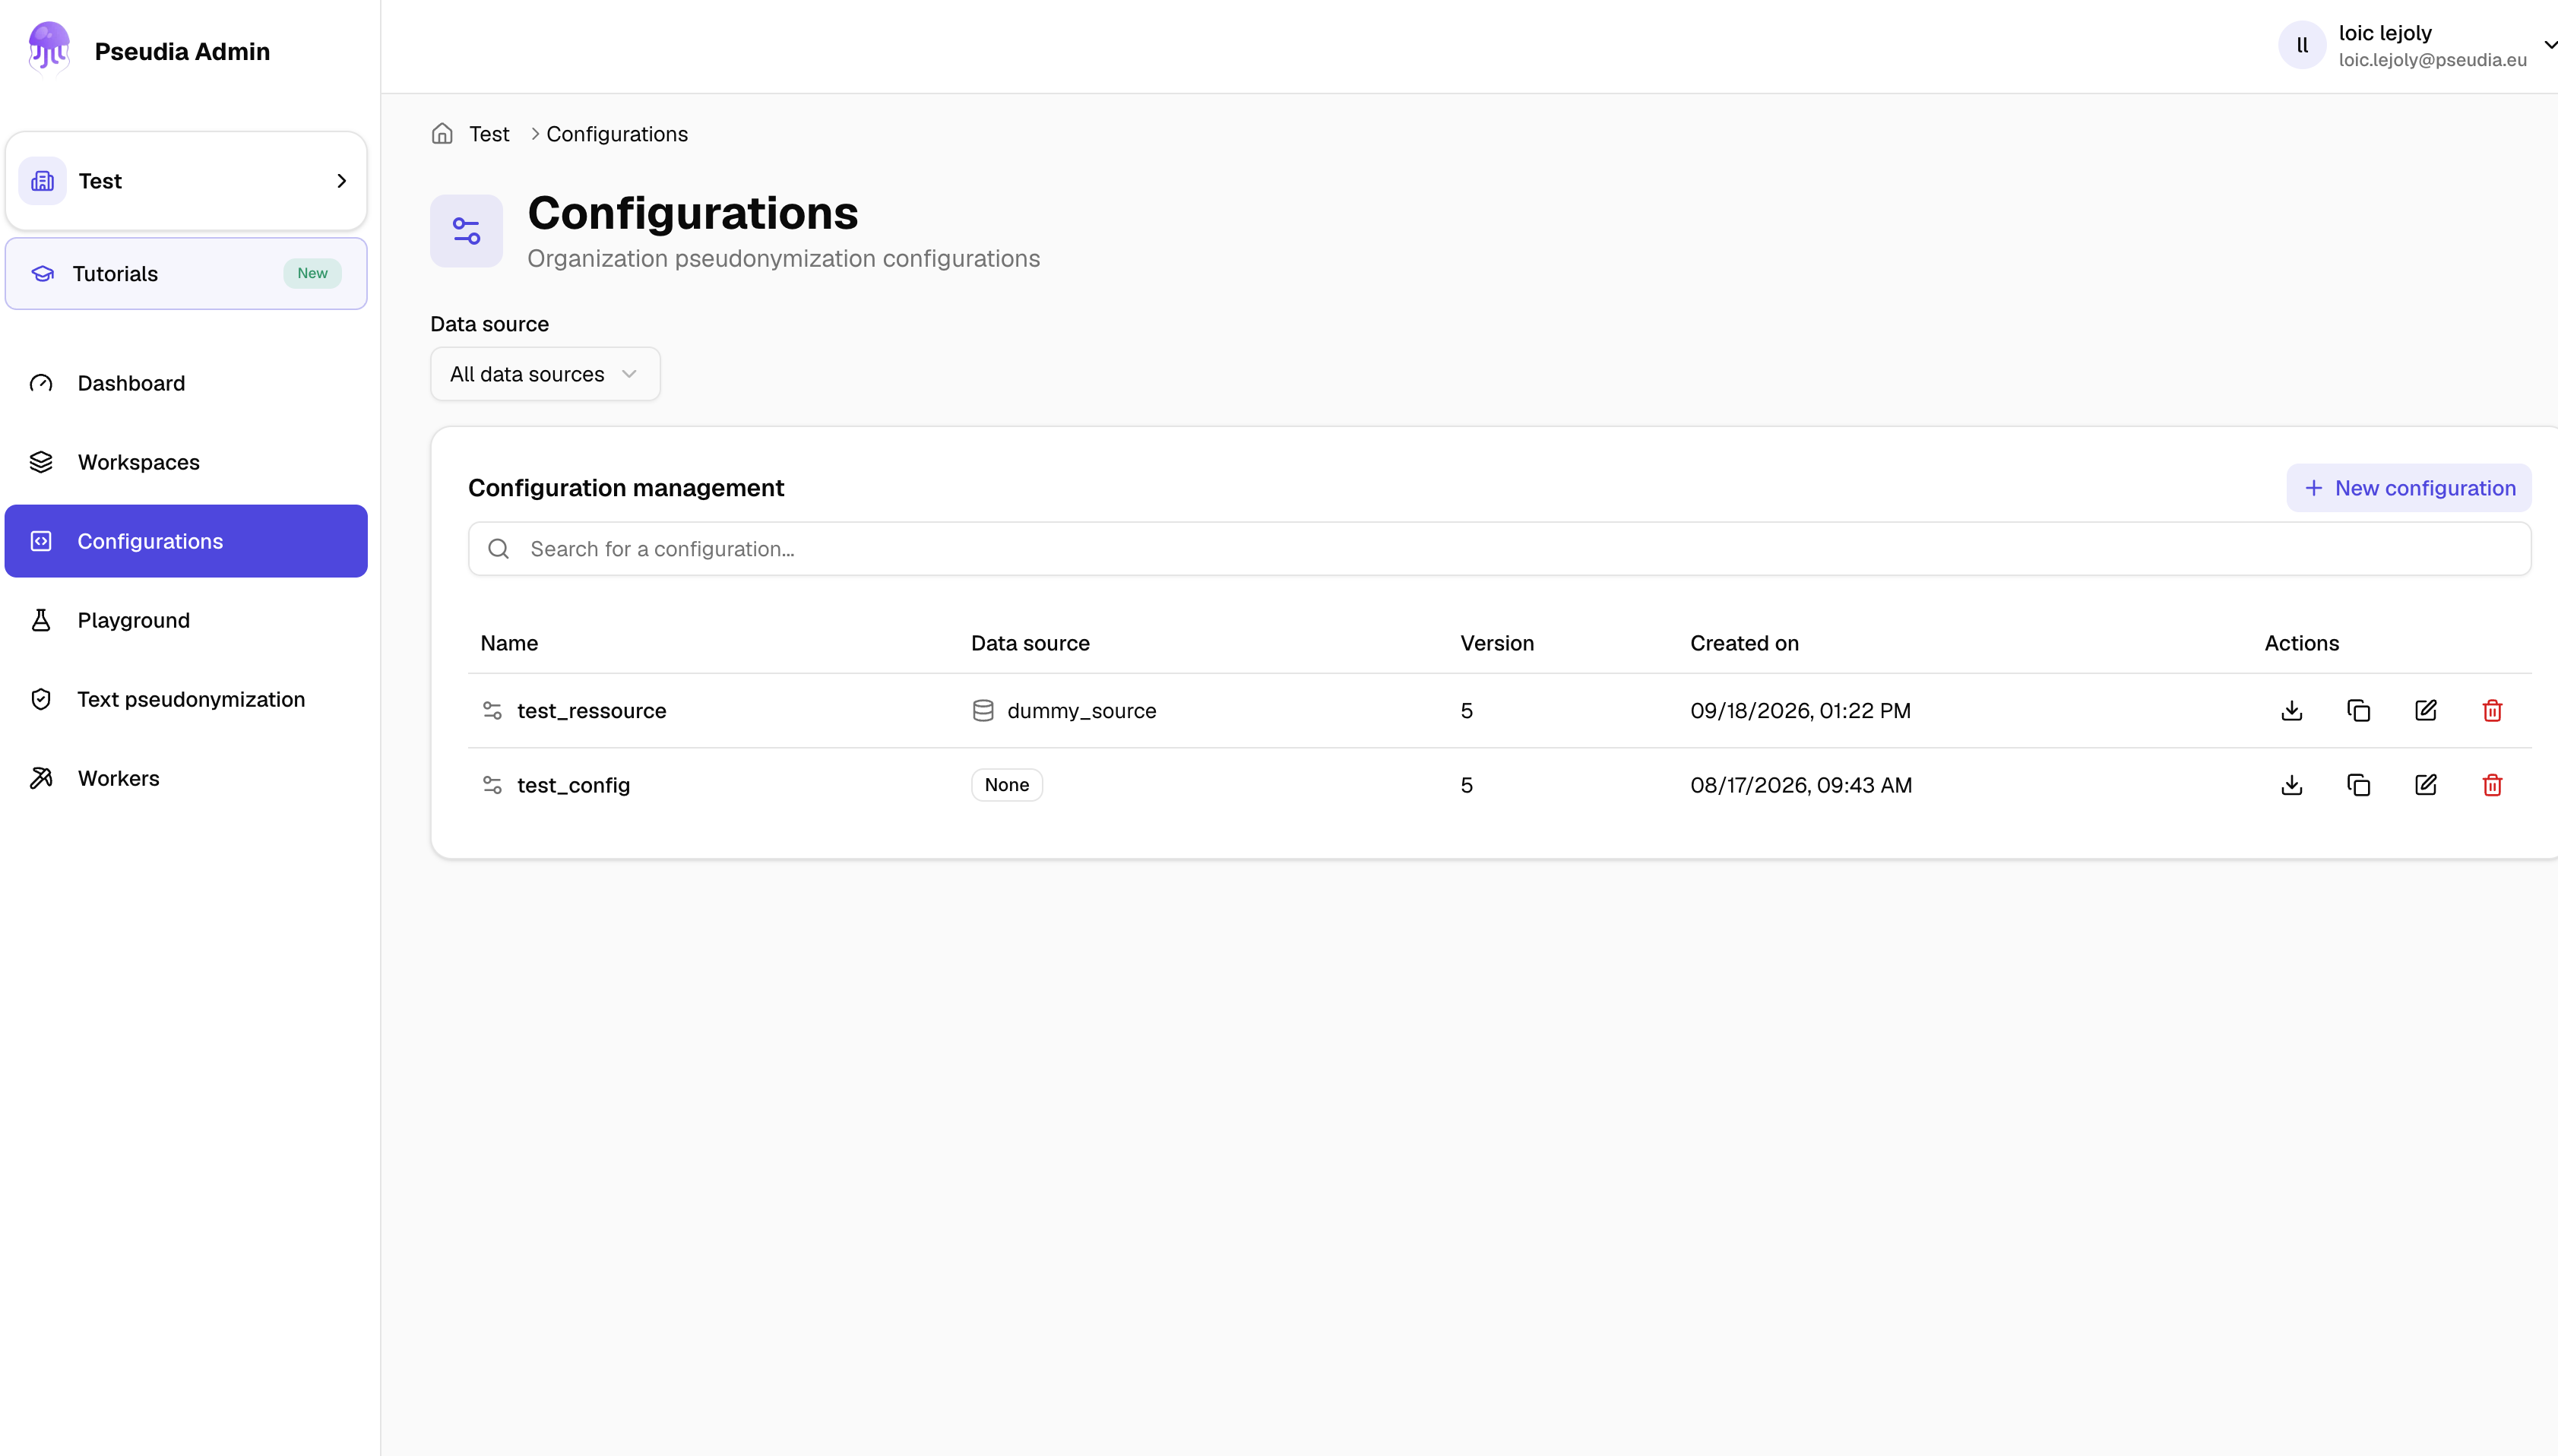
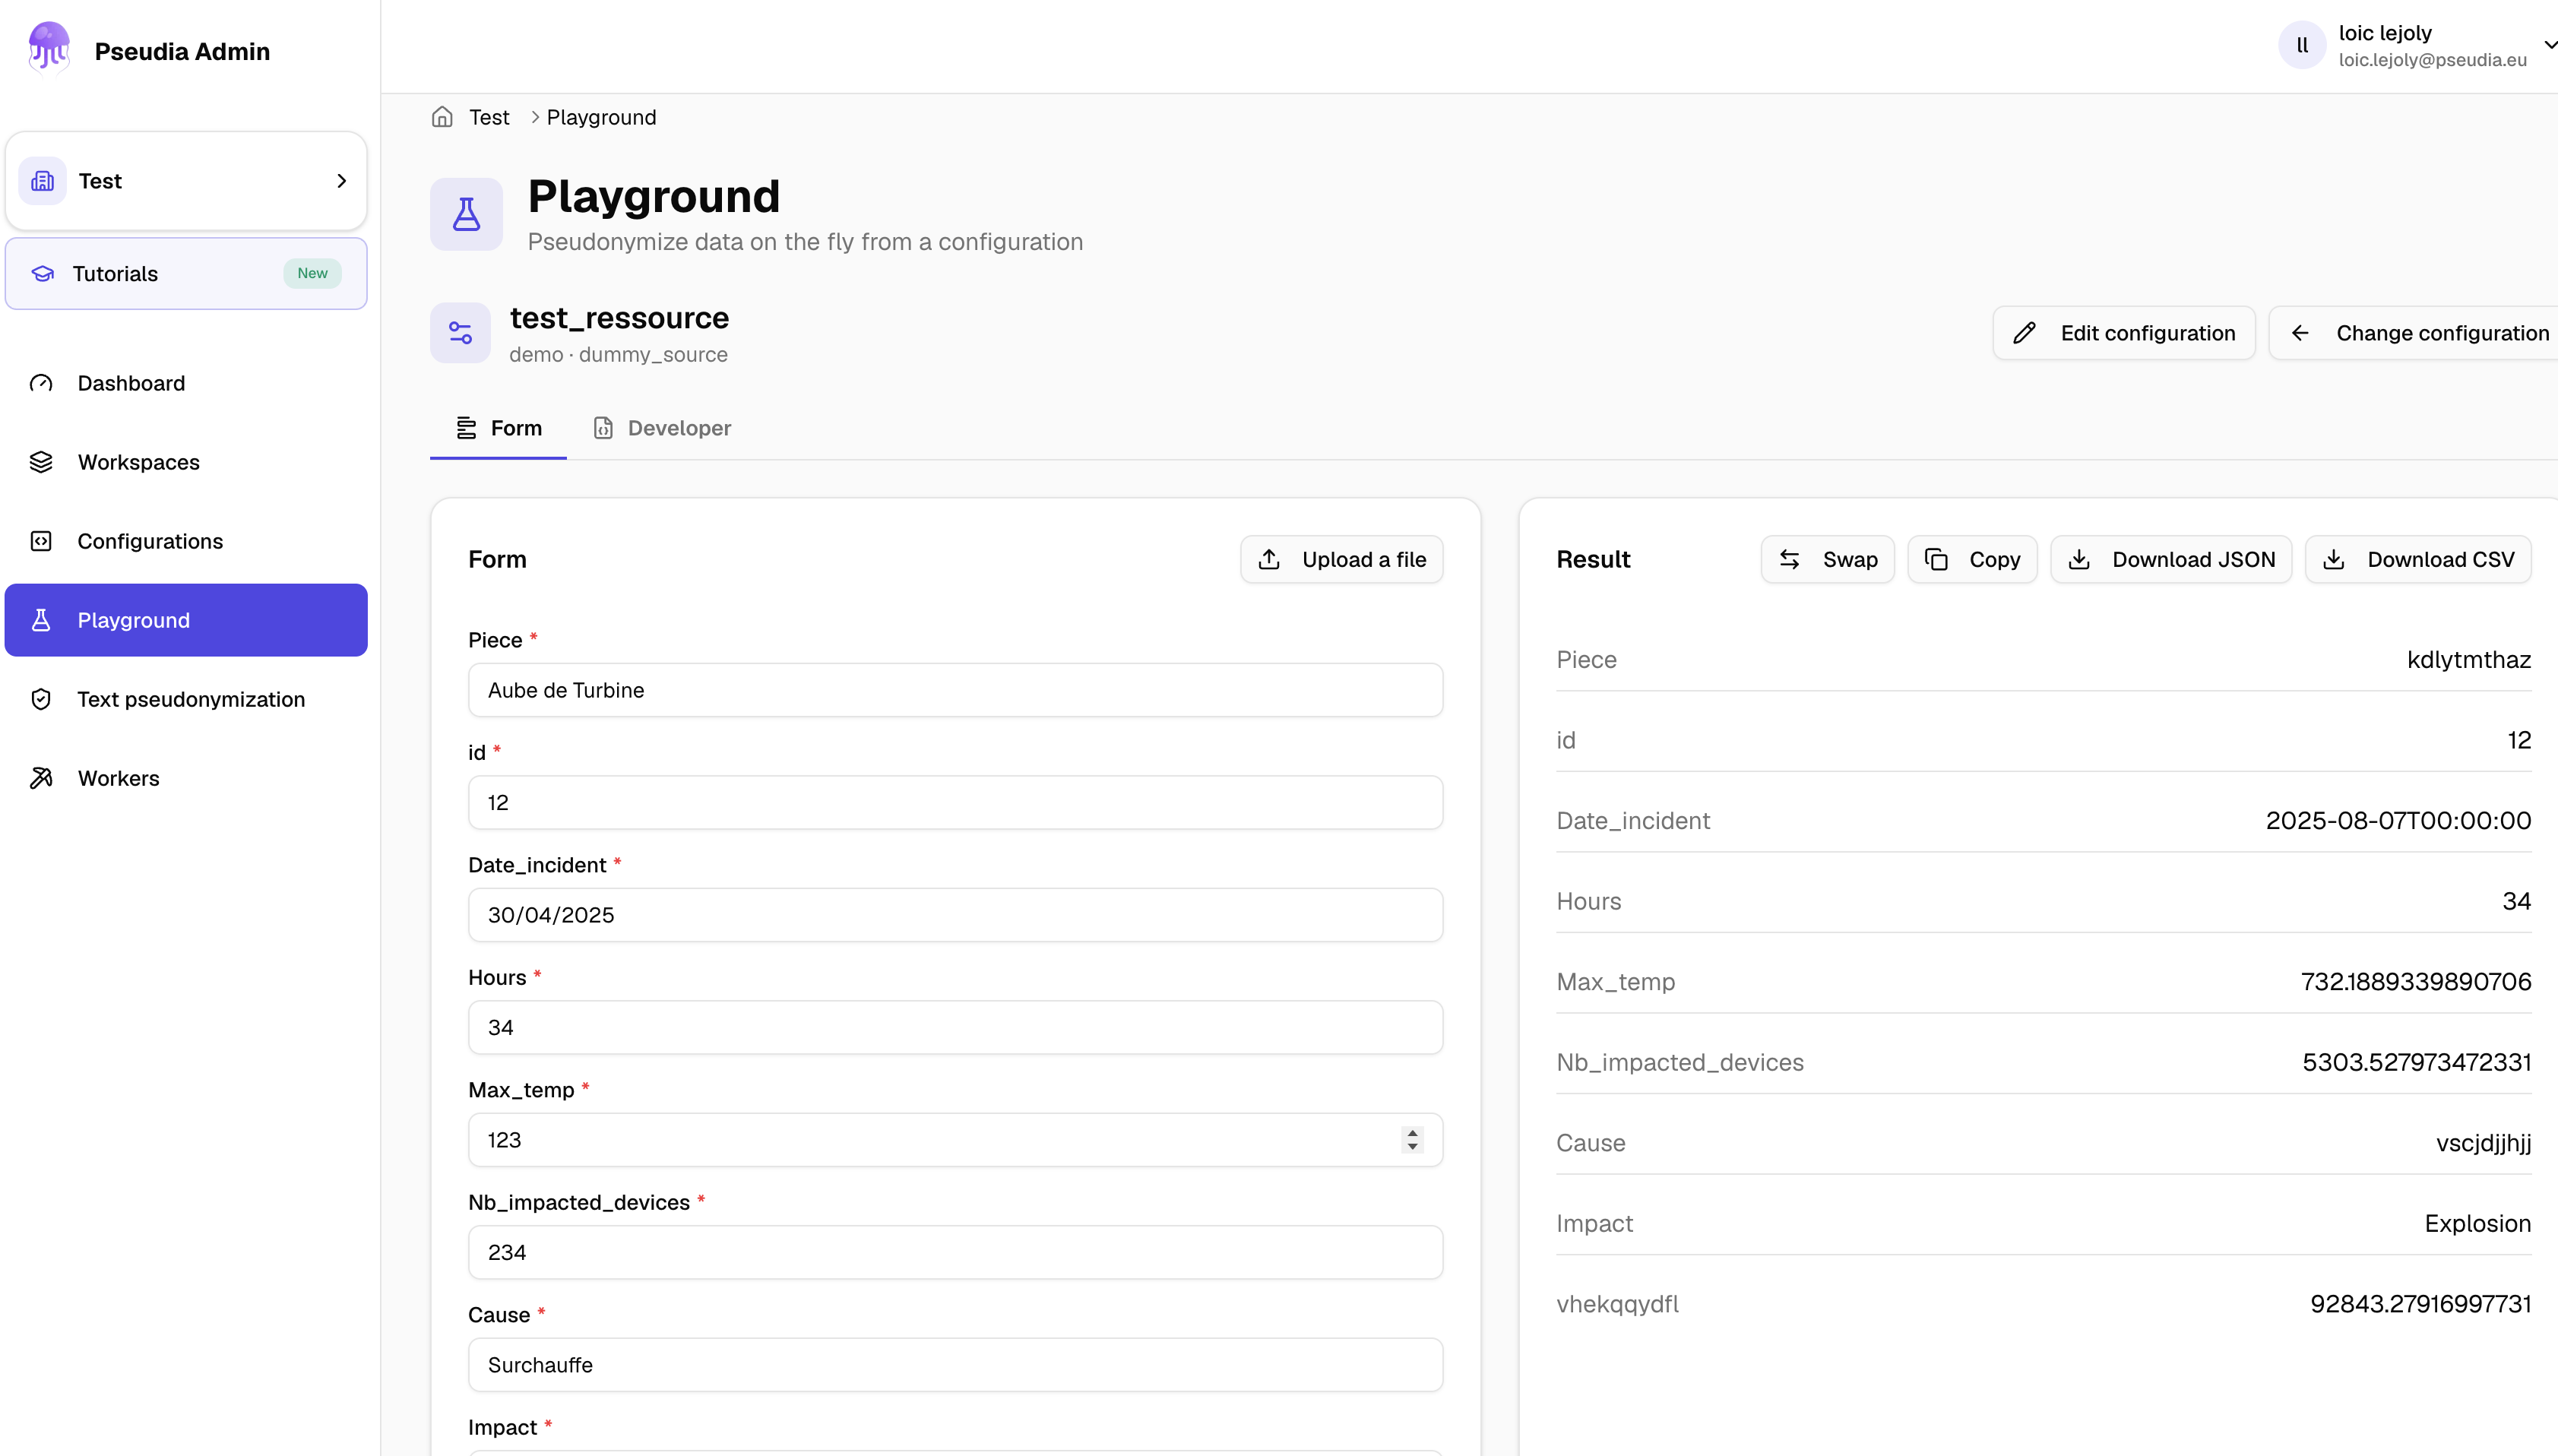
Test a configuration on a handful of sample records before connecting a real source, perfect for quick checks or configurations that have no source yet.
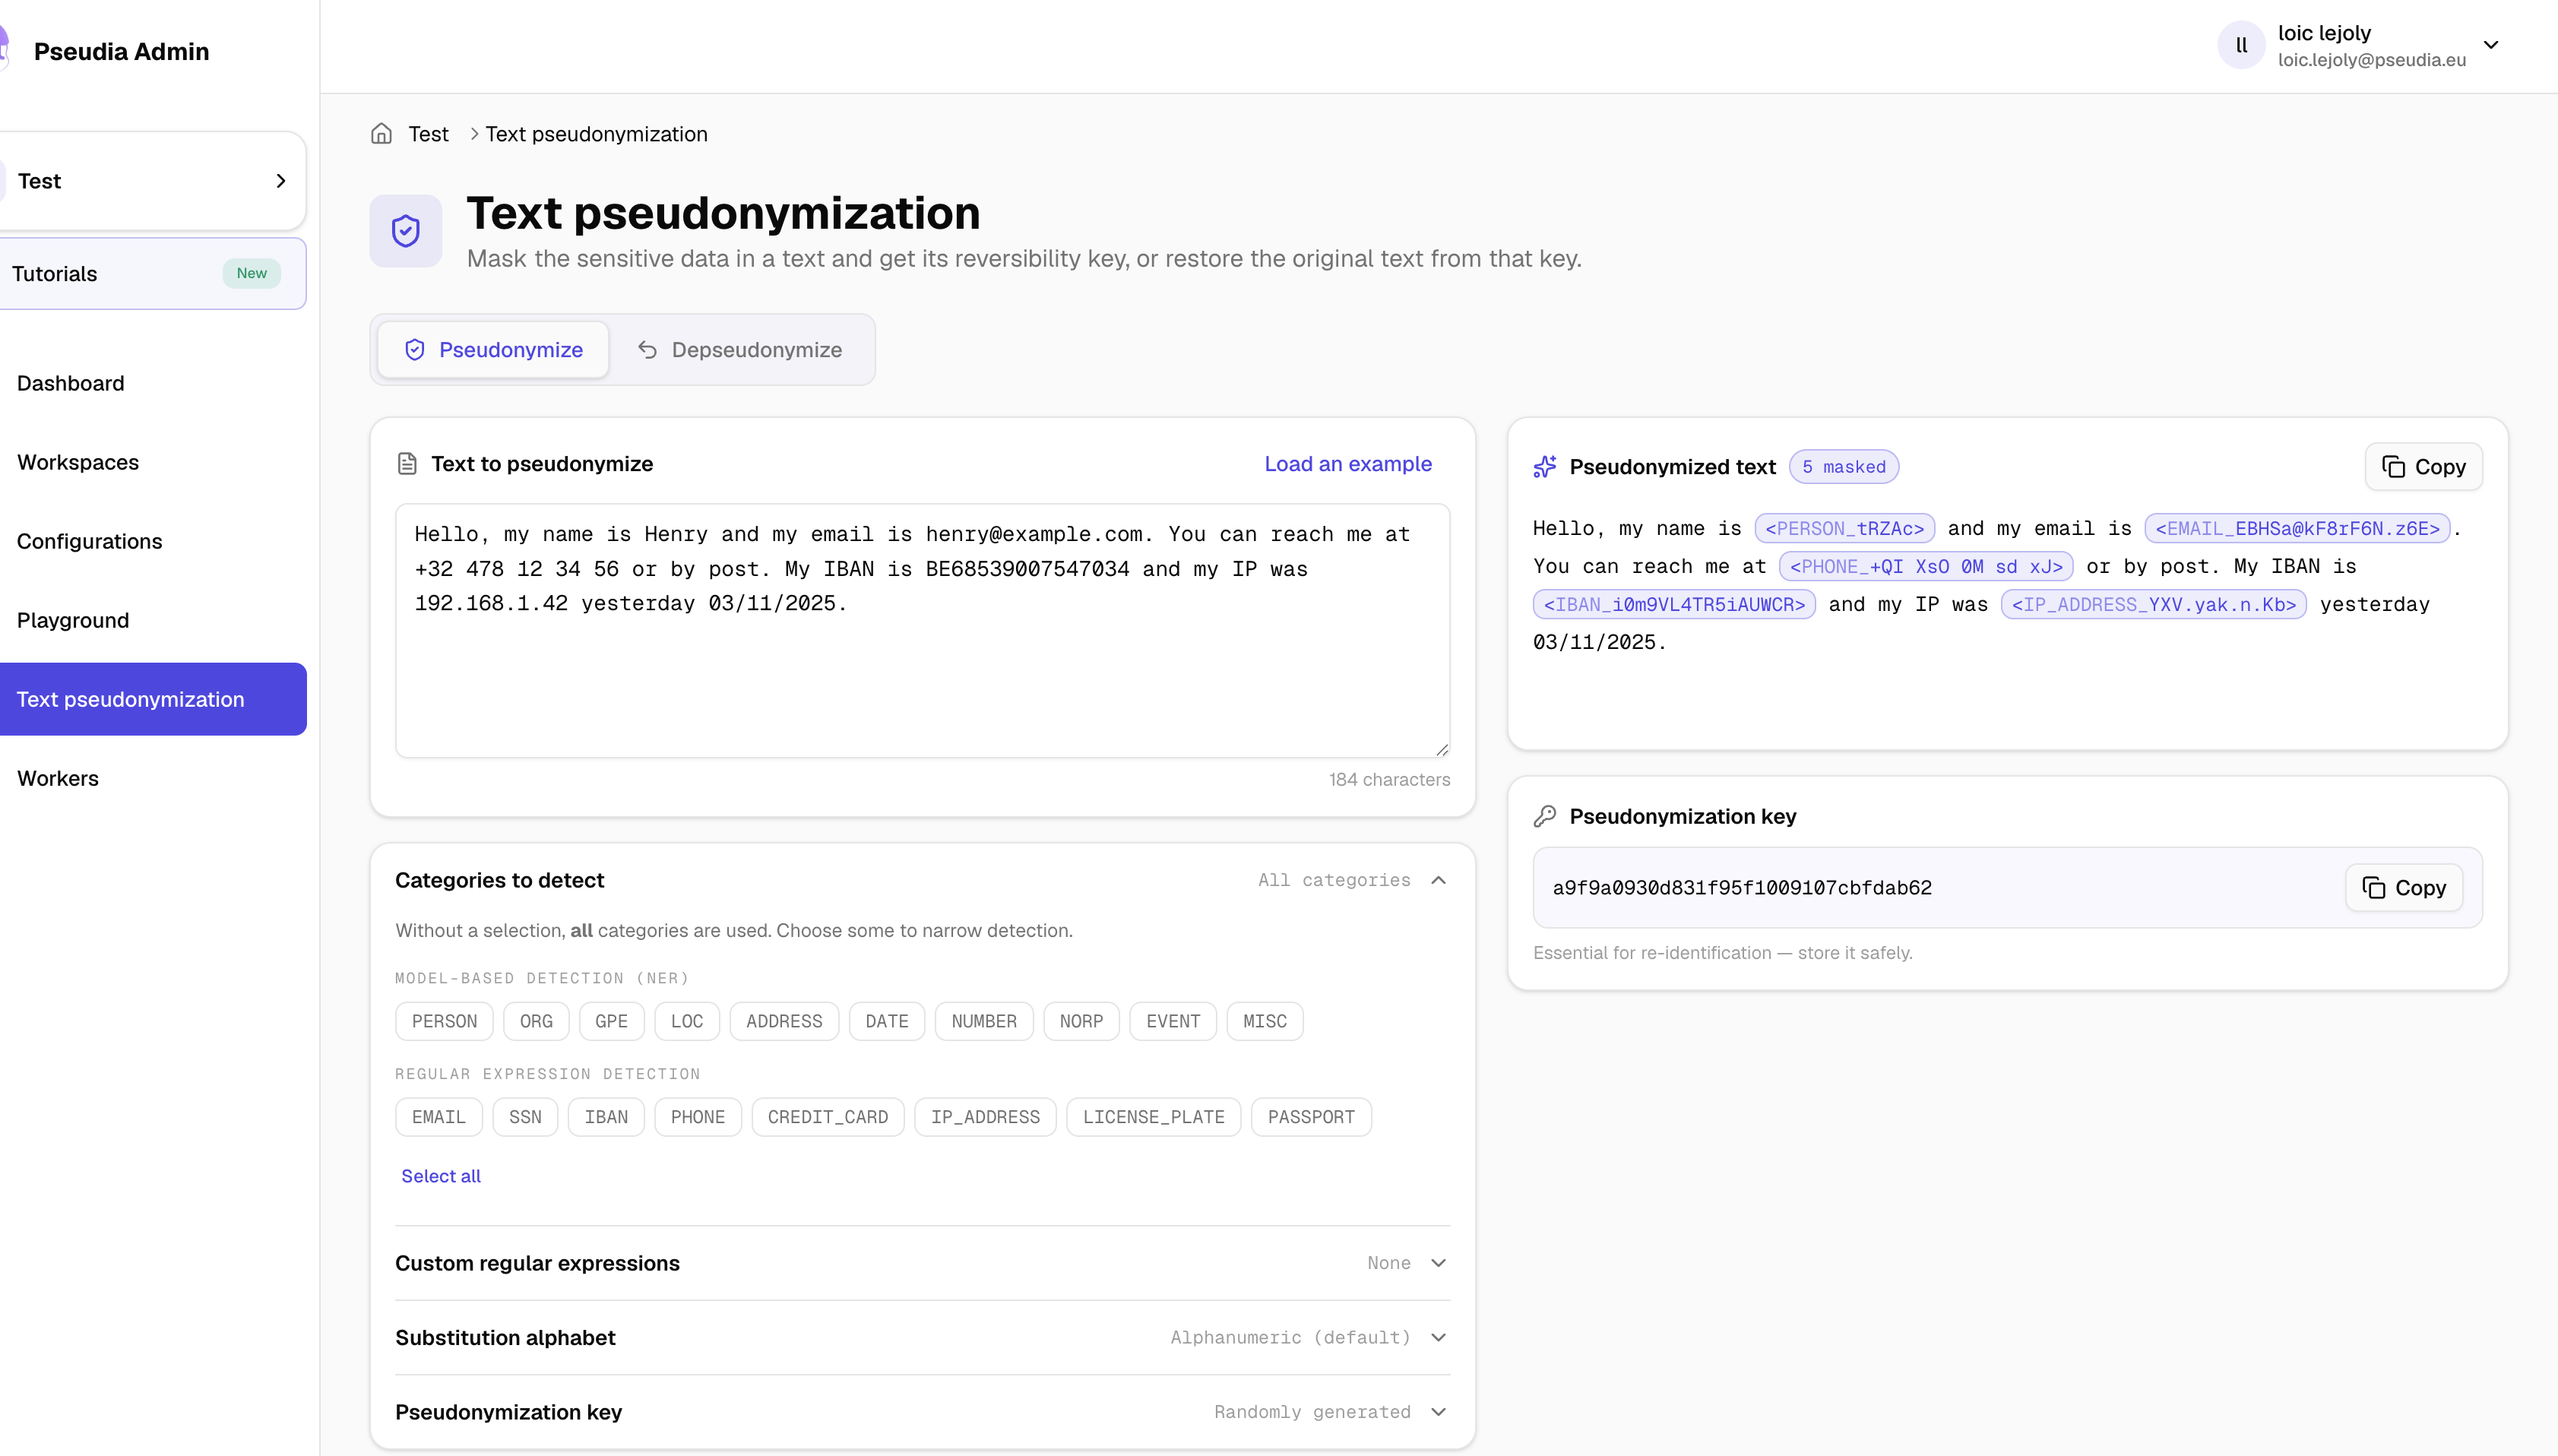
Detect and redact sensitive information directly inside unstructured text, such as emails, notes, or support tickets.
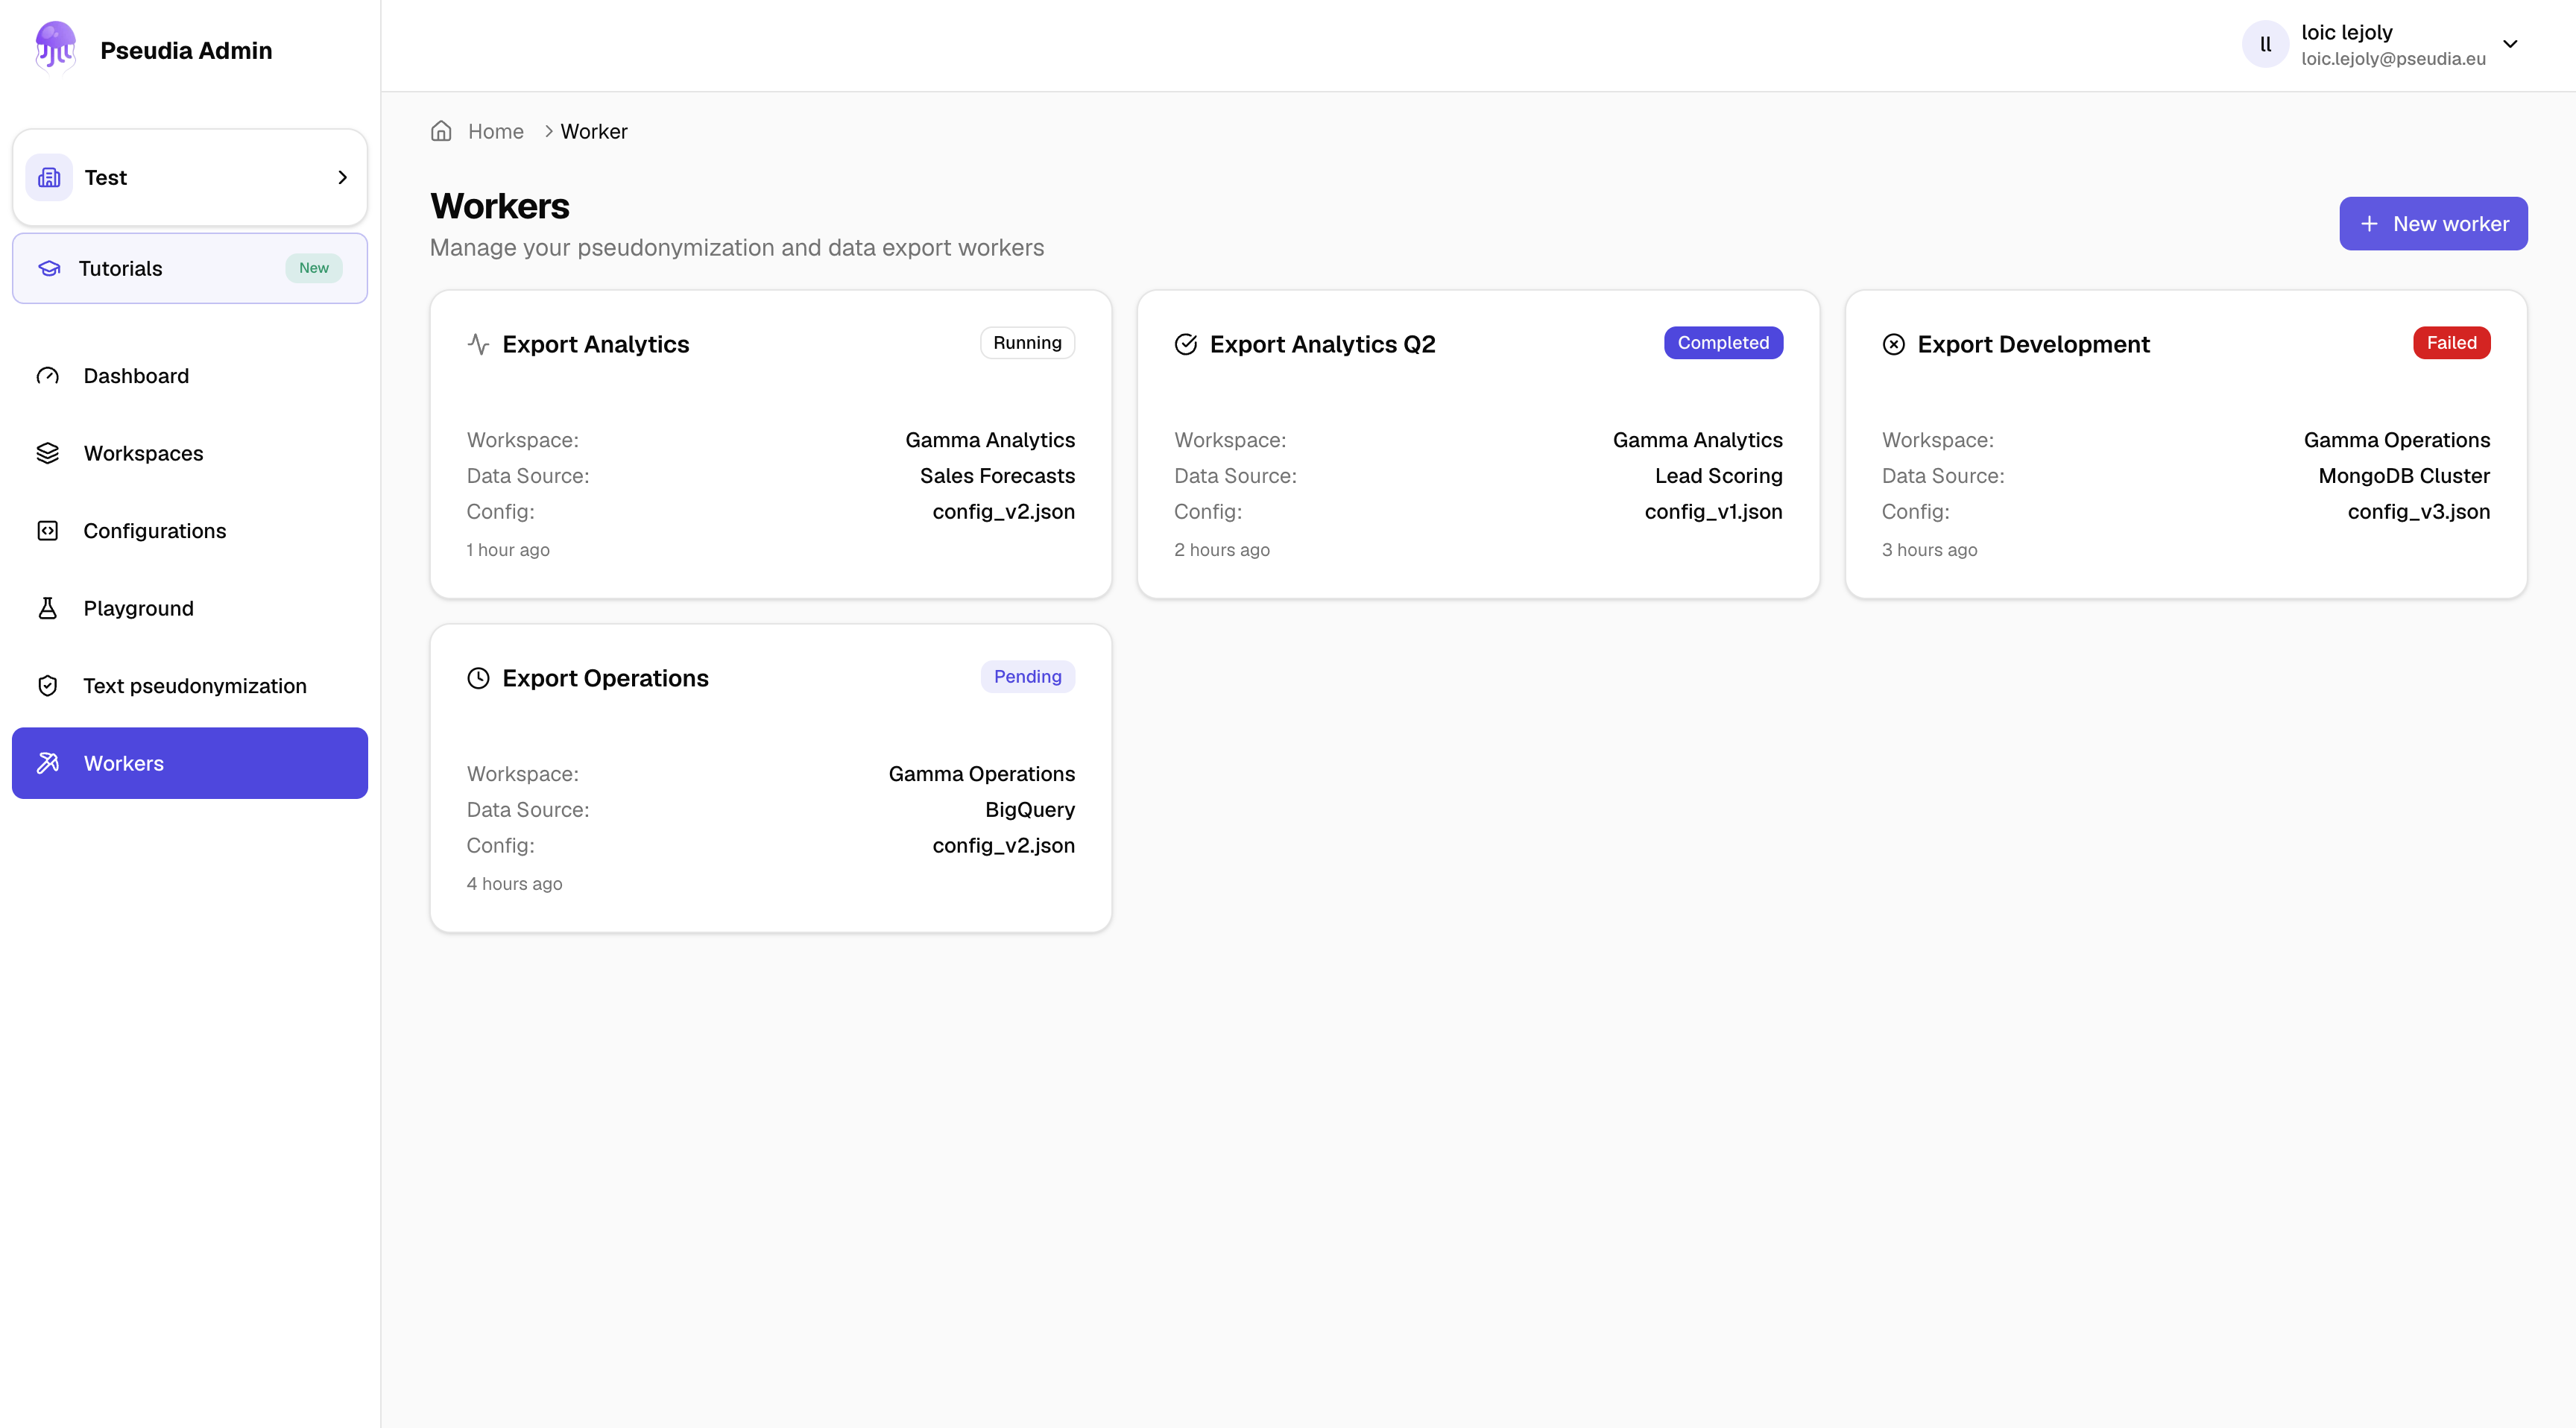
Execute your pseudonymisation configuration as a batch job over an entire data source, monitored from a single dashboard.
An architecture where keys never co-reside with pseudonyms. A leak exposes pseudonyms, not people.
CISOGenerate realistic datasets on demand while preserving structure, distribution, and relational consistency.
InnovationPseudonymise prompts, documents and RAG sources before they reach external LLMs. Your teams keep their preferred AI tools.
AIConfigure, trace, and export. Every processing activity is documented and auditable. Prove compliance, don’t just claim it.
DPOPlug in your own algorithms via API when our native functions don’t cover your specific sectoral needs.
FlexibilityDesigned and hosted in Europe. Zero data transfers outside the EU by default. On-premises deployment available.
EU SovereignBefore choosing, you need to know what is really being compared.
Only the name is stripped. Everything else (IBAN, age, postal code) still circulates freely. By cross-referencing just a few fields, 87 % of individuals can be re-identified. (MIT, Sweeney)
Mathematically grounded. Each individual becomes indistinguishable from at least k others, so re-identification by cross-referencing becomes very unlikely.
A model generates a fictional dataset statistically close to reality. No real individual appears in the output.
Real identifiers are replaced by consistent tokens or realistic fake values. Marie Dupont → psd_k8x2m. Indirect identifiers such as postcodes can be made less precise. Structure, distribution and relationships remain intact. A separate key allows controlled reversal, logged and audited.
¹ Pseudonymised data technically remains personal data as long as the re-identification key exists. GDPR applies. Pseudia drastically reduces real exposure risk, but does not replace the associated legal obligations.
Three steps. Secure. Sovereign. Reversible.
A practical, two-page checklist for security and data teams, coming soon. Leave your email and we'll send it to you as soon as it's available.
12 concrete checks to run before plugging real data into test, AI or analytics pipelines, covering data mapping, technique selection, key management, and how to make your process provable to a DPO.
20 minutes. Your use case. Not a generic pitch.